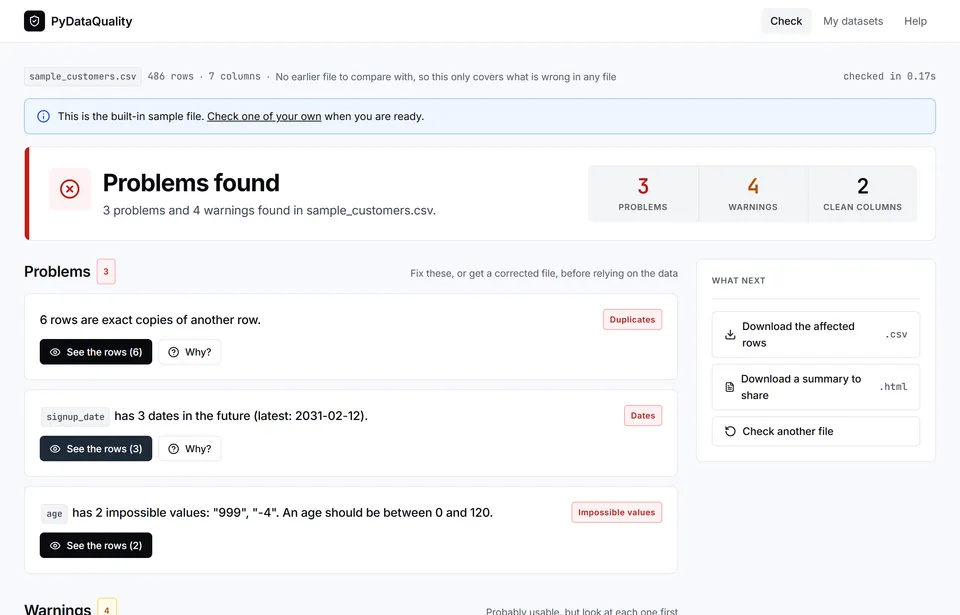
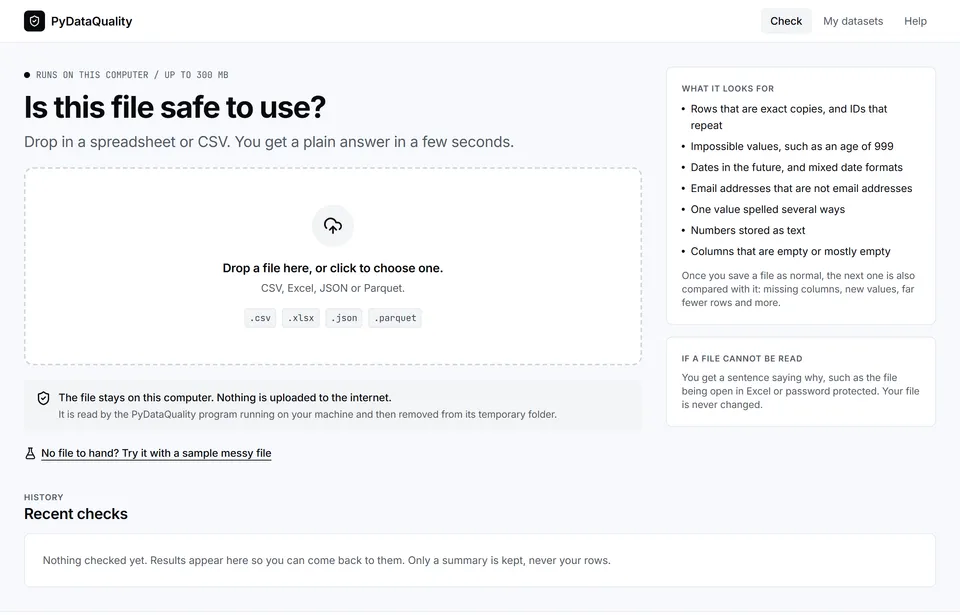
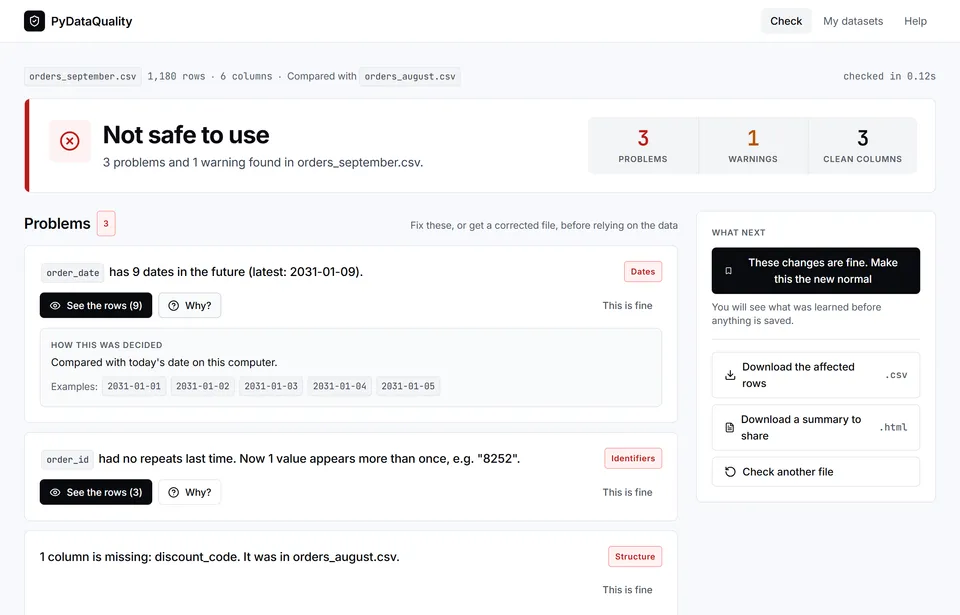
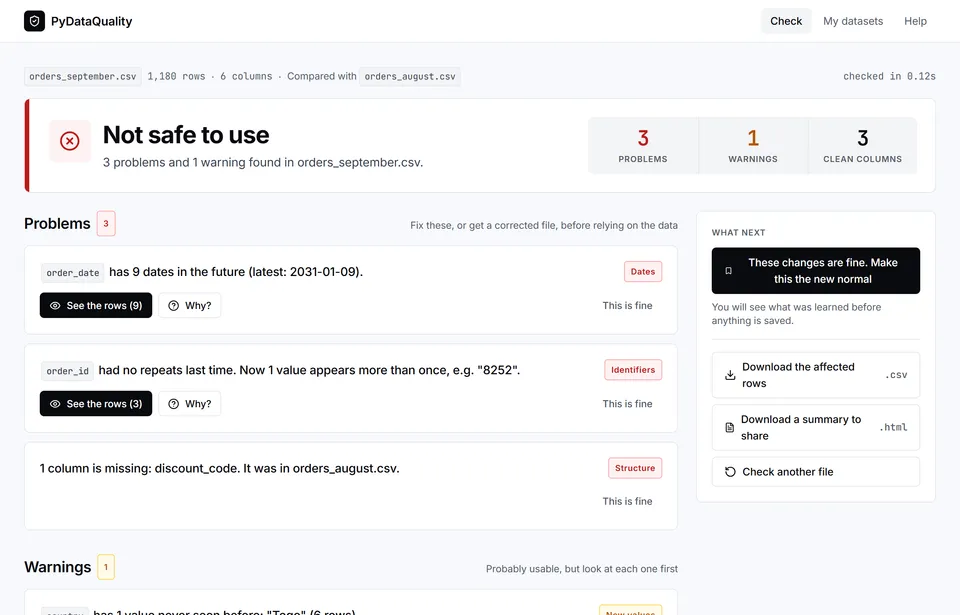
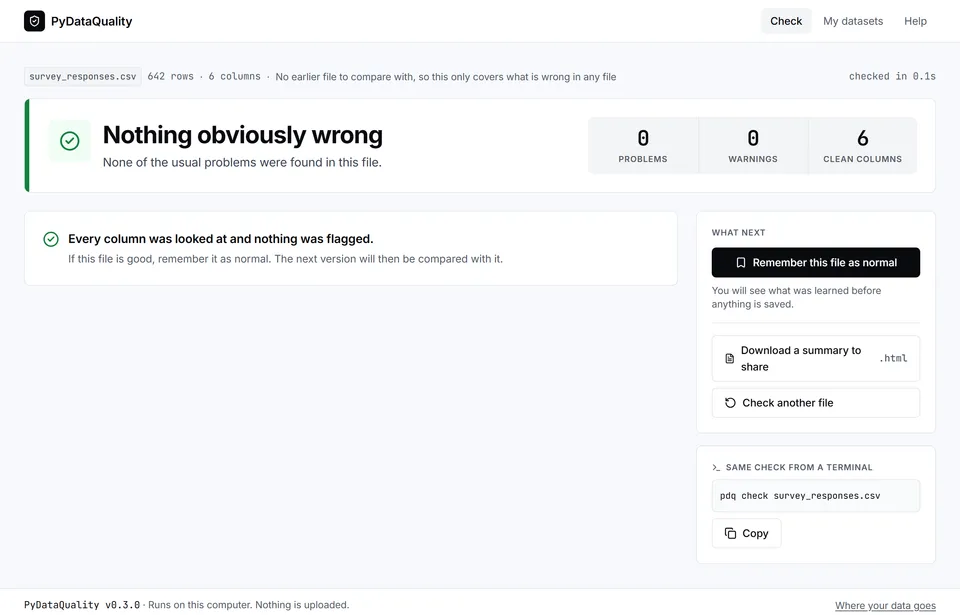
PyDataQuality tells you whether a data file is safe to use, and what changed since the last one, in plain language and on your own computer. It finds duplicates, repeated IDs, impossible values, future dates, mixed formats, invalid emails, inconsistent spellings and far-off numbers, then shows the exact rows behind each finding.
Quick start
pip install pydataquality

pdq check customers.csv      # is it safe to use?
pdq accept customers.csv     # remember this file as normal
pdq check customers_nov.csv  # what changed since last time?
pdq rows customers_nov.csv   # save the affected rows, with reasons
pdq ui                       # the same, in a page in your browser
In Python: result = pdq.check(df), then result.verdict, result.problems and result.bad_rows().
Research
PyDataQuality: An Actionable, Lightweight Data Profiling and Distribution Drift Detection Framework for Production Machine Learning Pipelines. Dominion Akinrotimi, 2026. Preprint on Zenodo, DOI 10.5281/zenodo.22211750. Each software release is archived under DOI 10.5281/zenodo.23344748. The paper is a preprint (not yet peer reviewed) and I am seeking a suitable journal; suggestions are welcome.
Learn the maths behind it
Need this kind of work done?
I take on data engineering, analytics, machine learning and research projects, and I speak and train teams on data and AI.